-Challenge
Strict security policies blocked external LLM providers, slow inference hurt user experience, and low-fidelity extraction from complex PDFs reduced answer reliability.
Mobiele ontwikkeling
Kunstmatige intelligentie
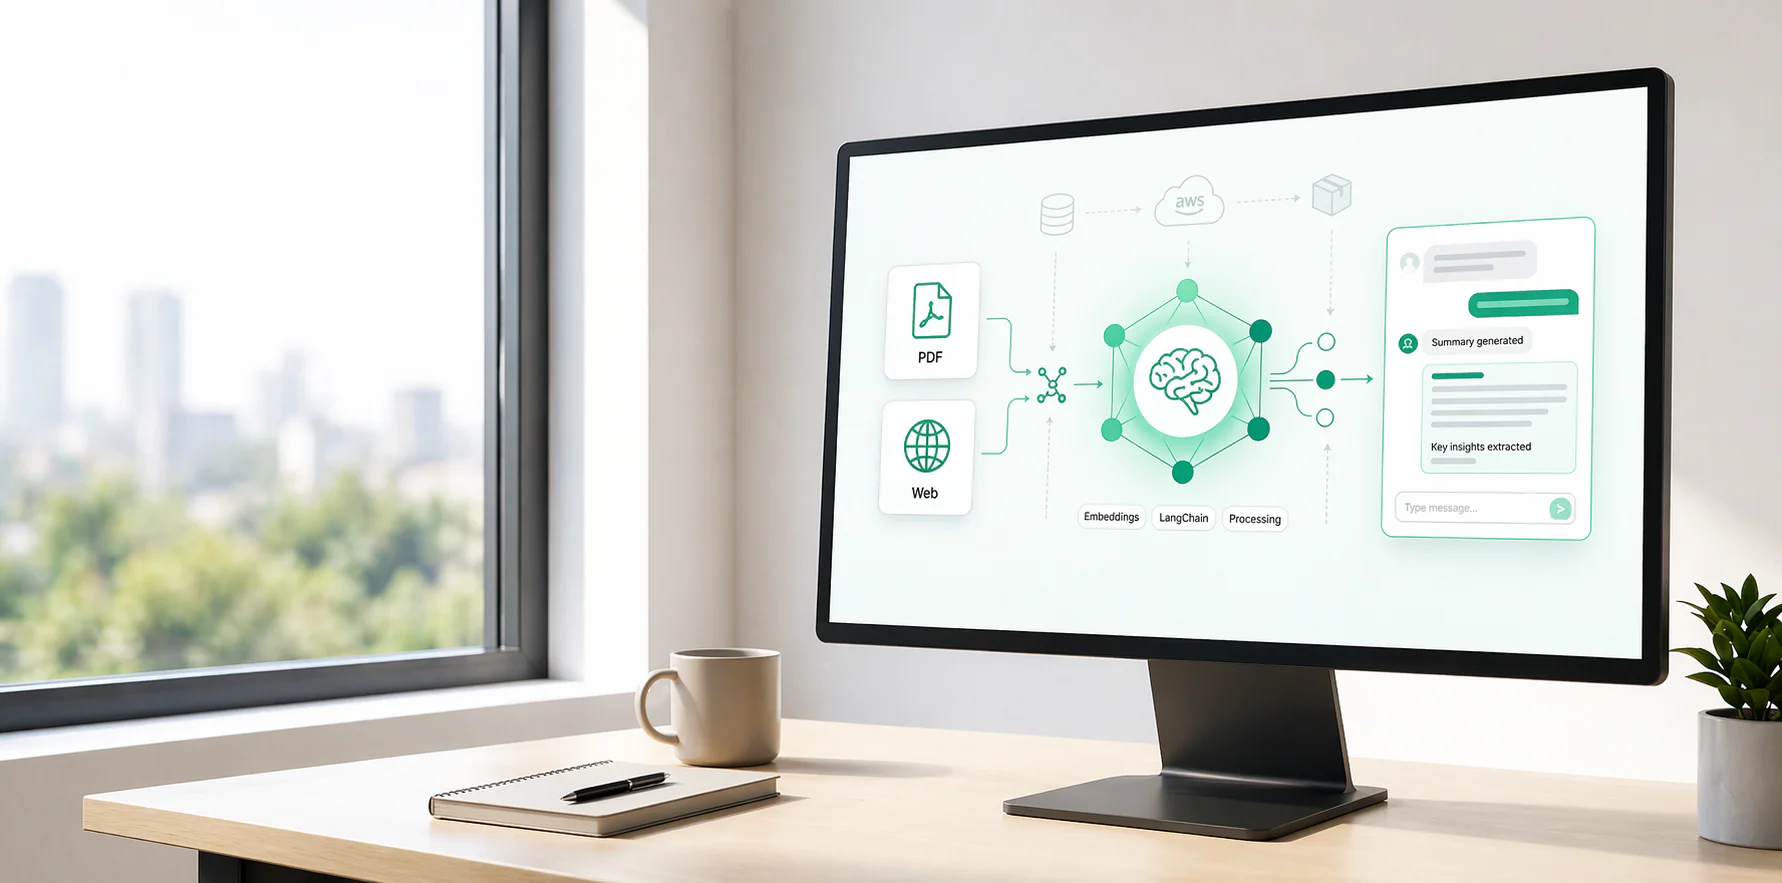
Deployment of a Llama LLM on AWS SageMaker for private inference with optimized latency and a customized RAG data ingestion pipeline using AWS Textract. The solution keeps all data inside the client's AWS VPC while delivering near real-time chatbot responses.
Strict security policies blocked external LLM providers, slow inference hurt user experience, and low-fidelity extraction from complex PDFs reduced answer reliability.
Private VPC deployment on SageMaker, latency optimization through model/runtime tuning, and Textract-based ingestion for better handling of tables and mixed document layouts.
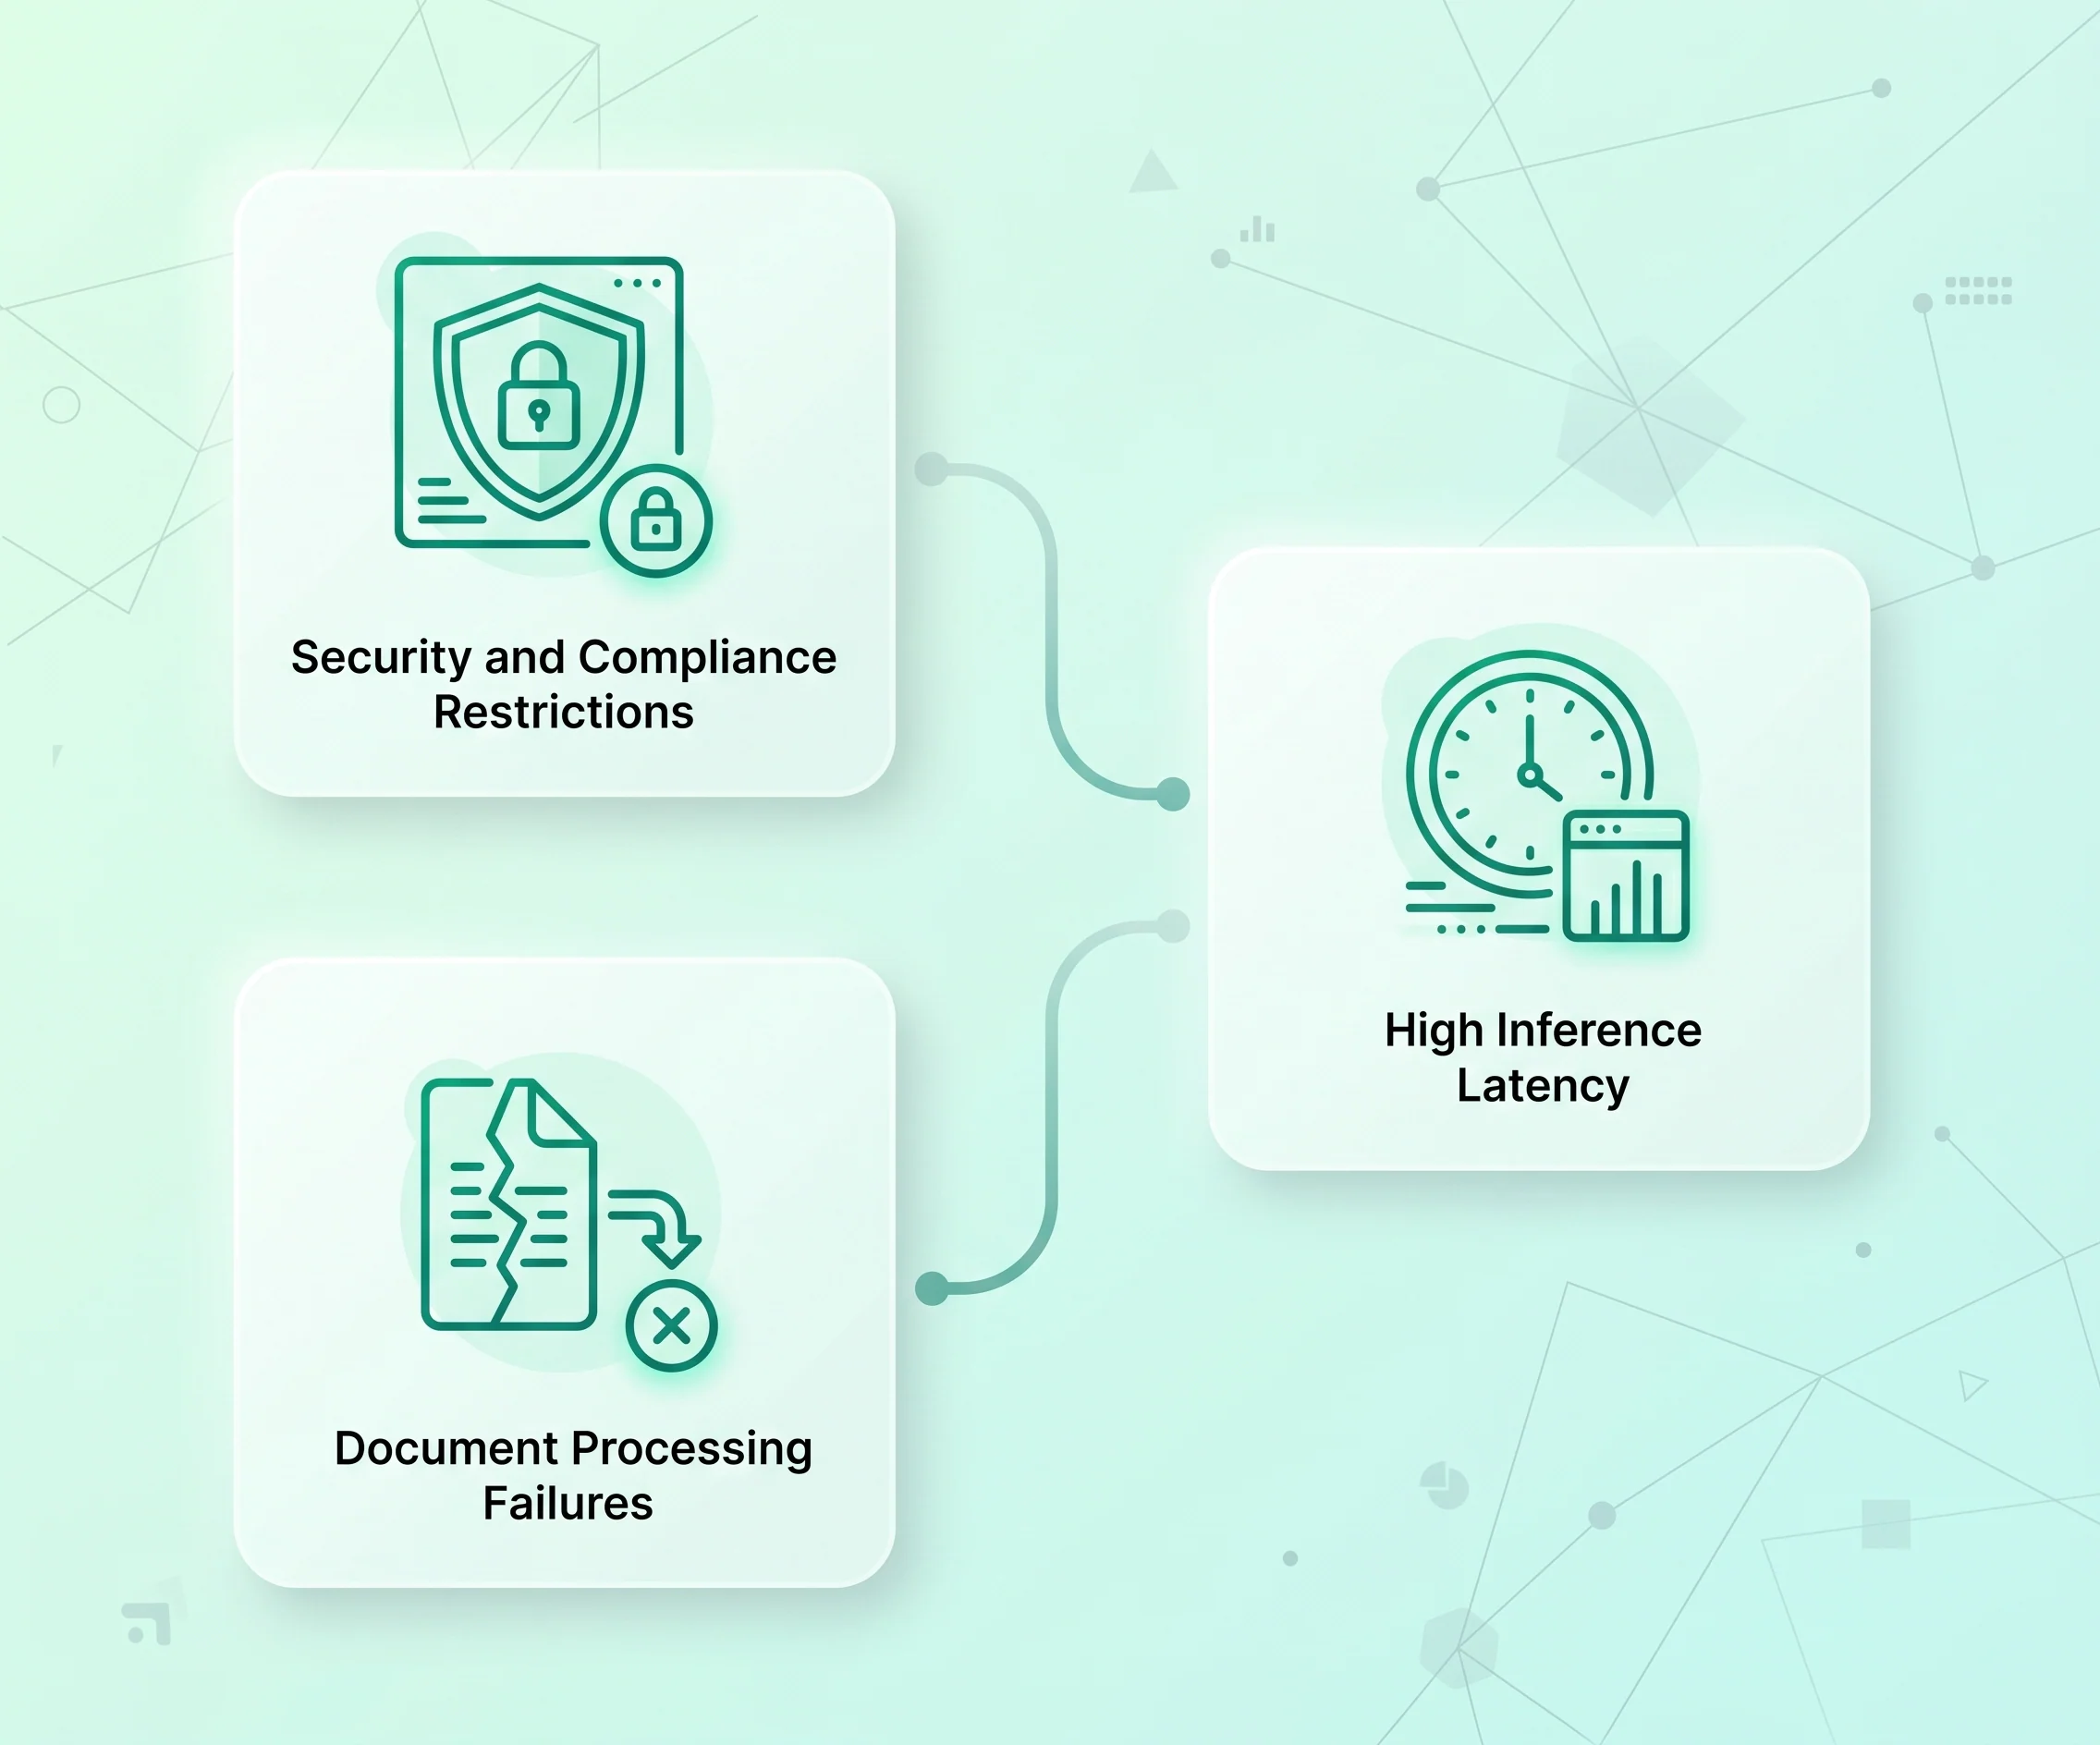
The client could not rely on externally hosted LLM services due to strict compliance and data sovereignty requirements, limiting adoption paths for modern AI.
The existing setup produced delayed chatbot responses because inference configuration and runtime performance were not optimized for responsive interactions.
The pipeline struggled with table-heavy and mixed-layout PDFs, causing weak extraction quality and reducing confidence in generated answers.
Deploy private model infrastructure, optimize response speed, and strengthen document ingestion so compliance and performance are both met in production.
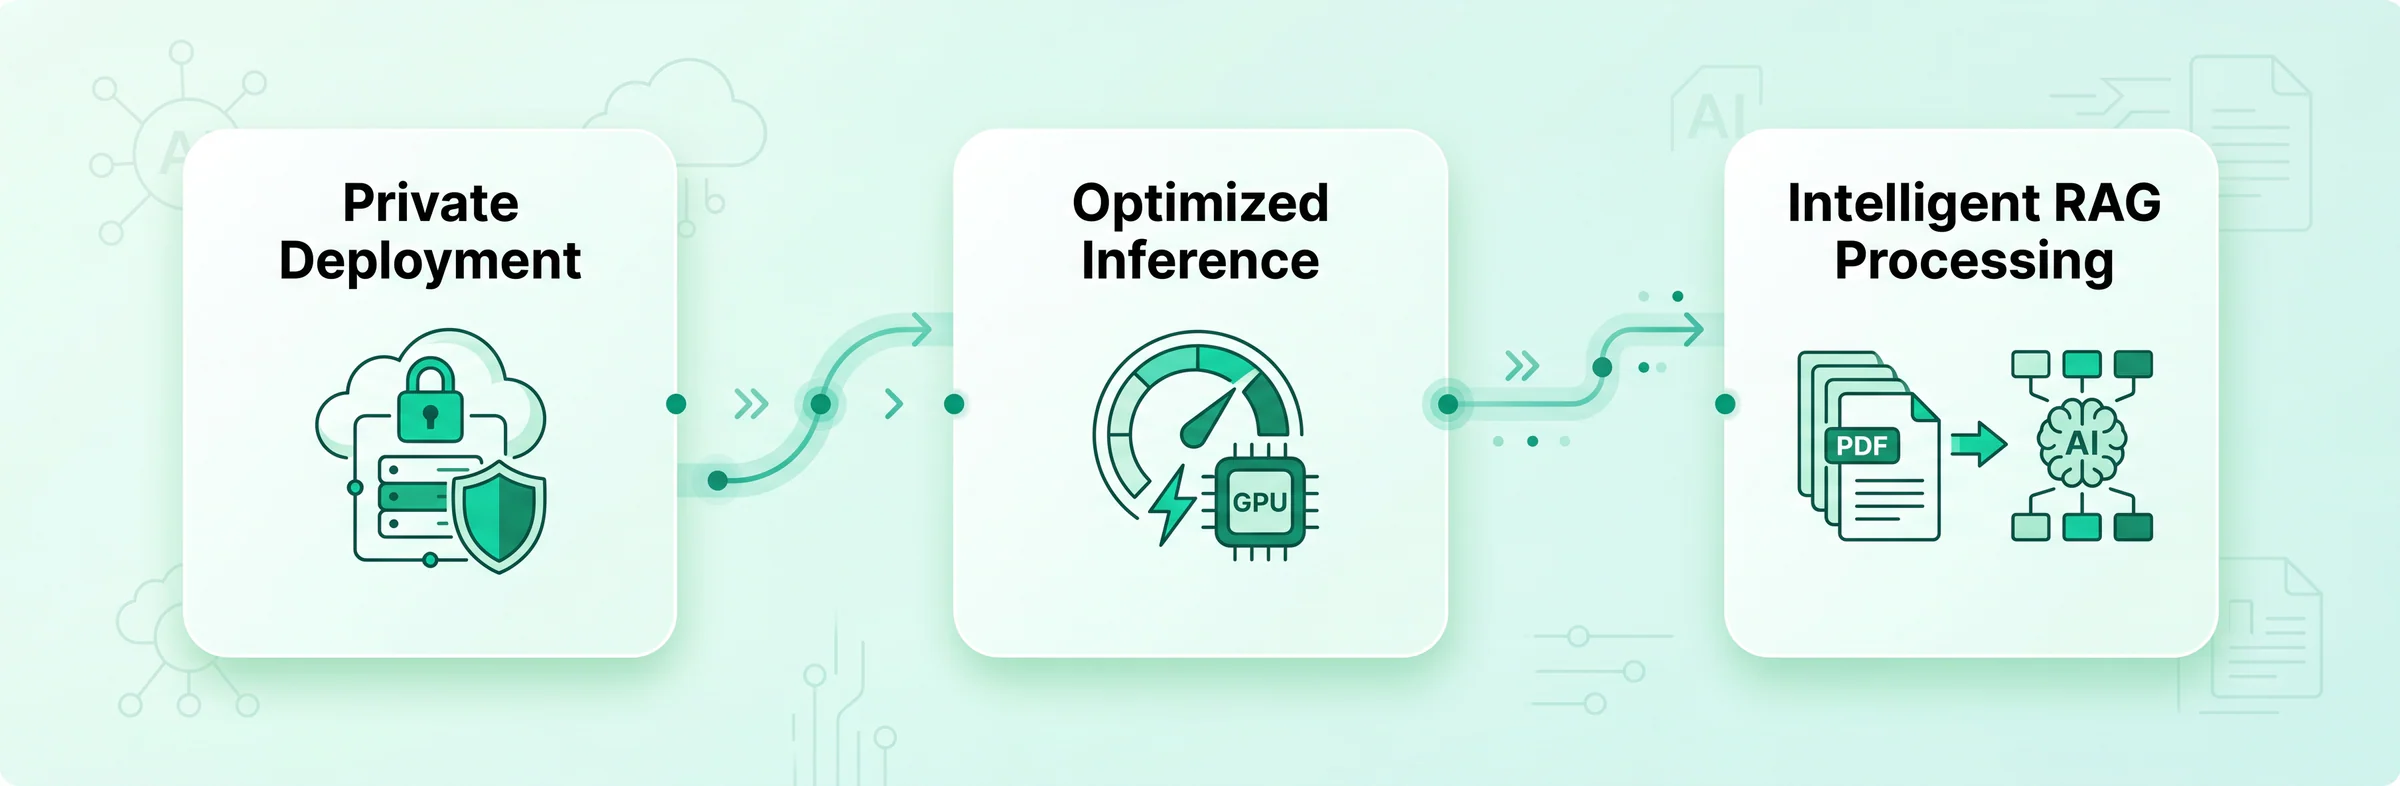
Llama model hosted fully inside the client's AWS VPC to keep data in controlled infrastructure and satisfy compliance boundaries.
Configuration tuning, GPU utilization improvements, and streaming-oriented response strategy reduced latency for near real-time chatbot interactions.
Document ingestion pipeline rebuilt to accurately extract, structure, and chunk content from complex PDFs with tables and mixed formats.
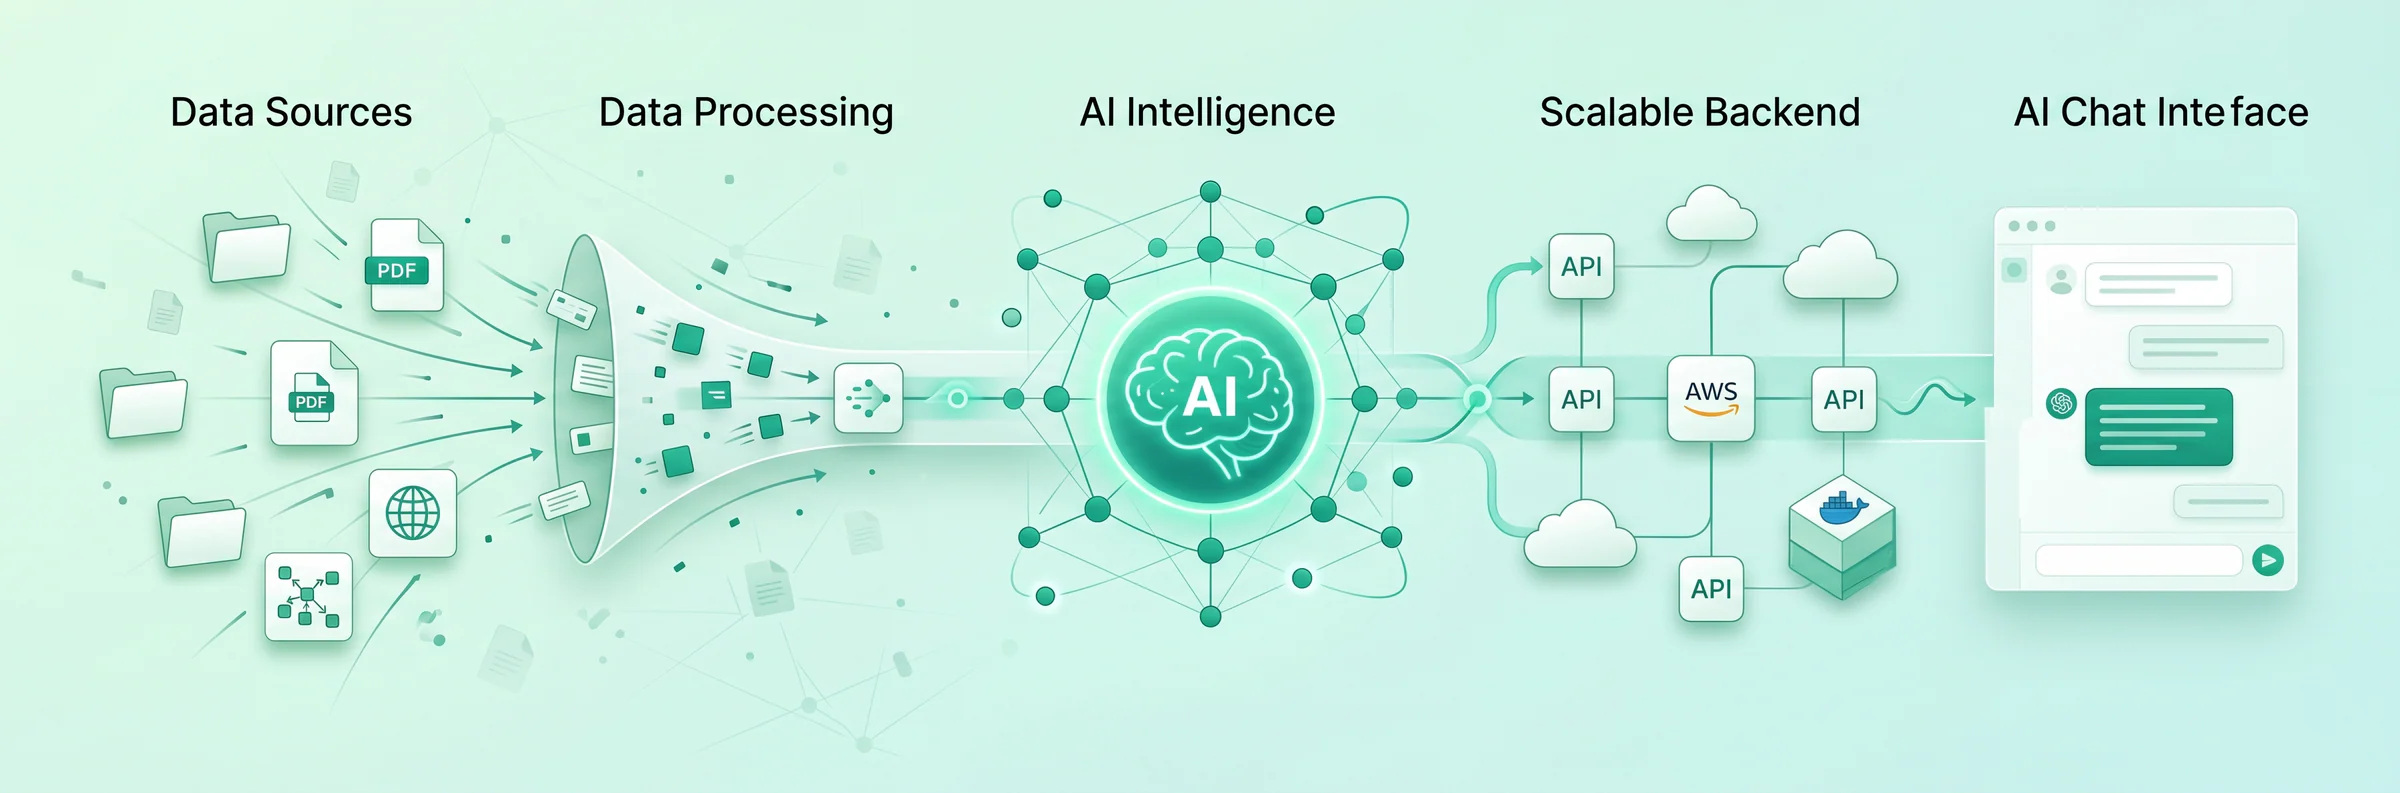
Llama model deployed on AWS SageMaker inside the client's VPC for full infrastructure control. This delivered private inference without depending on third-party model hosting.
Model/runtime tuning, GPU optimization, and response-streaming oriented behavior improved end-to-end latency and enabled near real-time chatbot performance.
Customized ingestion pipeline with AWS Textract improved extraction from table-rich and mixed-layout PDFs, raising retrieval quality and answer precision across document types.
The implementation improved speed, reliability, and governance readiness while preserving full data control in a private deployment model.
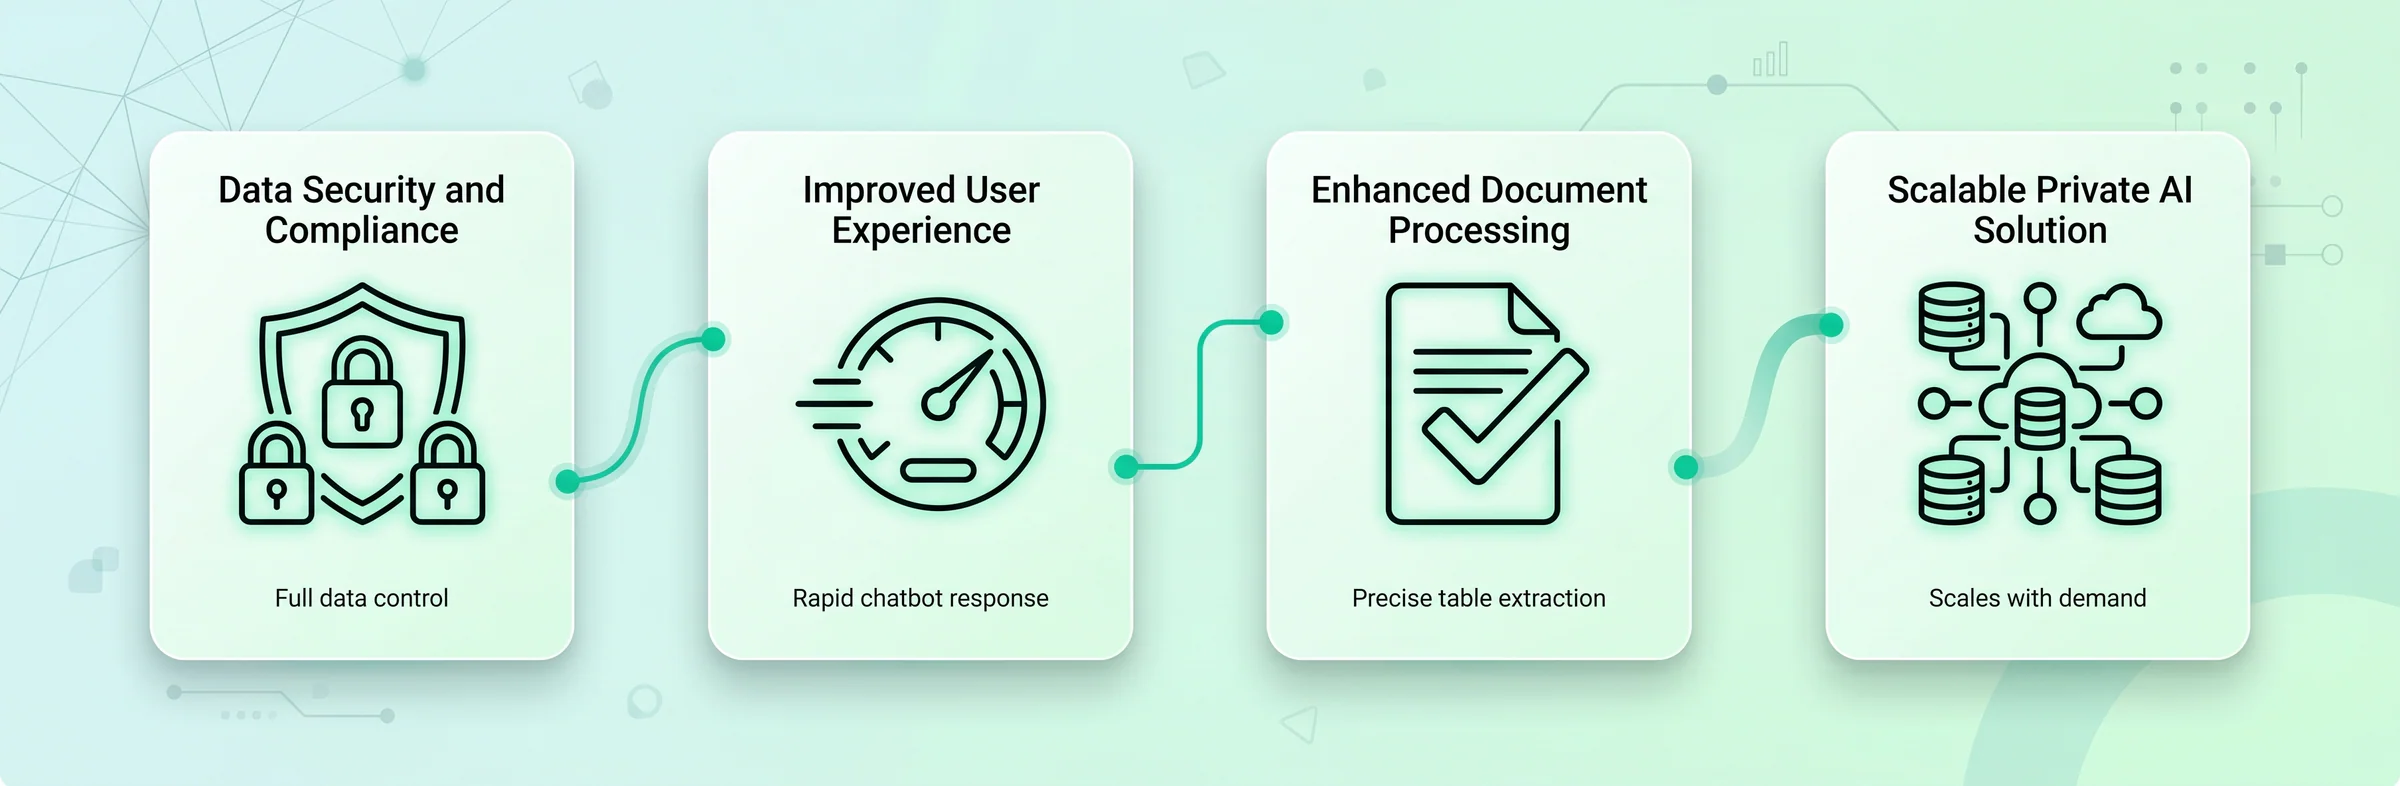
Project proves strict compliance environments can deploy private LLM systems without sacrificing practical response speed.
Latency tuning is not cosmetic. It directly controls user trust, chatbot adoption, and operational value.
Textract-based processing for tables and mixed layouts improved retrieval fidelity and made outputs more dependable in real workflows.
Architecture aligned to real enterprise limits: data sovereignty, compliance policy, and performance requirements at the same time.

© auteursrechten 2026 Sifars – Mobile & Web App Development Company. Alle rechten voorbehouden Privacybeleid